
Every team says they run blameless postmortems. Few actually do.
The phrase gets used as a badge of maturity, proof that an engineering org is “past” finger-pointing. But sit in on most incident reviews and you’ll still hear it: “Why didn’t you catch that in review?” “Whose change was this?” The meeting is called blameless. The room isn’t.
This gap matters because postmortems only work when people tell the truth. The moment someone feels like they’re defending themselves, they start editing the story, leaving out the shortcut they took, the alert they muted, the deploy they rushed. You lose the exact details that would have prevented the next incident.
This post covers what a blameless postmortem actually is, where teams get it wrong, and a process you can run starting with your next incident.
What a Blameless Postmortem Actually Is
A blameless postmortem is a structured review of an incident that treats human error as a symptom, not a root cause. Instead of asking “who caused this,” it asks “what about our systems, processes, and defaults made this mistake possible, and even likely?”
This isn’t about being nice. It’s a methodological choice, popularized by Etsy’s engineering team and now standard practice at organizations like Google and Netflix, built on a simple premise from safety science: individuals rarely fail in isolation. They fail inside systems that set them up to fail: unclear runbooks, missing guardrails, alert fatigue, unrealistic deploy windows.
Blameless doesn’t mean consequence-free. It means the consequence isn’t aimed at a person. It’s aimed at the gap in the system that let a reasonable person make a reasonable-seeming decision that turned out badly.
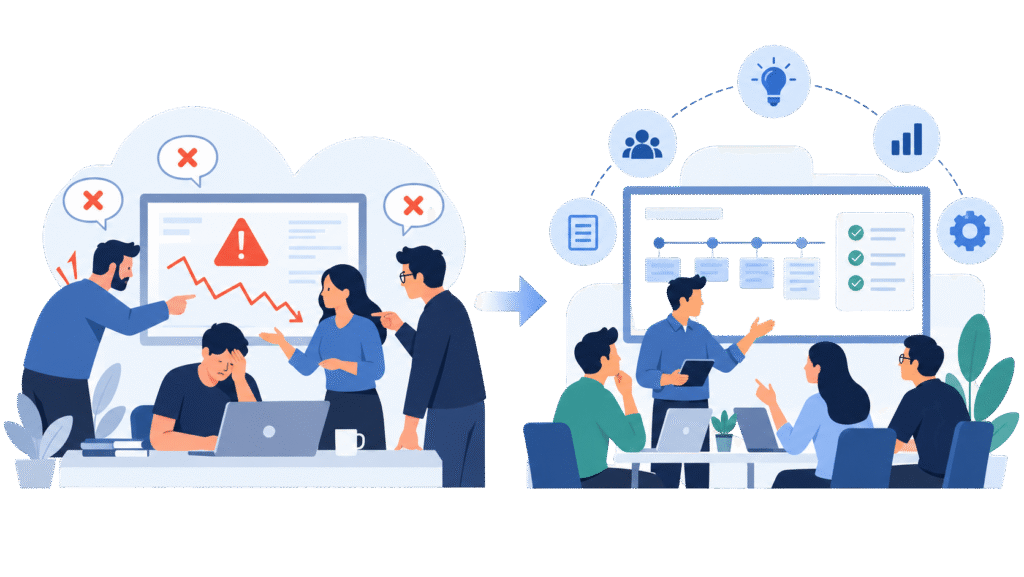
Blame-Driven vs. Blameless: What Actually Changes
The difference isn’t just tone. It changes what gets discussed, documented, and fixed.
| Blame-Driven Postmortem | Blameless Postmortem | |
|---|---|---|
| Central question | Who made the mistake? | What allowed the mistake to happen? |
| What people share | Sanitized, defensive version of events | Full timeline, including the near-misses and workarounds |
| Documentation | Vague ("a configuration error occurred") | Specific ("the config was deployed without the staging check because staging was broken for three days") |
| Follow-up actions | "Be more careful," retraining | Fix the tooling, guardrail, or process gap |
| Repeat incident | Common, same root cause resurface | Rare, the systemic issue actually gets addressede |
| Team behavior over time | People hide problems until they escalate | People flag issues early, before they become incidents |
The last row is the real payoff. A team that trusts the postmortem process will surface small problems voluntarily. A team that doesn’t will let small problems compound until they can’t be hidden anymore, which is usually when they become expensive.
Common Misconceptions About Blameless Postmortems
“Blameless means no accountability.” It means accountability is aimed at the system, not the individual. The engineer who pushed the change is still accountable for helping fix the gap that let it ship unsafely; they’re just not accountable for having been human under time pressure.
“Blameless means we can’t name what happened.” The opposite. Vague language (“an error occurred”) is usually what blame-avoidance produces, ironically. A genuinely blameless writeup is specific: which service, which deploy, which decision point, in plain language, because nobody’s worried about how it reflects on them.
“This only applies to major outages.” The habit is built on small incidents. If you only run postmortems for the incidents that page executives, you never practice the muscle for the incidents that actually teach you something: the near-misses that didn’t quite become outages.
“The facilitator’s job is to keep things positive.” The facilitator’s job is to keep the conversation focused on systems and timelines, not to suppress hard questions. “Why did the rollback take 40 minutes?” is a legitimate, necessary question. “Why didn’t you know the rollback would take 40 minutes?” is not.
How to Actually Run One
Before the Meeting
Assign a facilitator who wasn’t directly involved in the incident. This is the single highest-leverage decision you’ll make. Someone close to the incident, even with the best intentions, will unconsciously steer the conversation toward or away from their own actions.
Build a factual timeline first, separate from the discussion of causes. Pull it from logs, alerts, deploy history, and chat transcripts, not memory. Memory is where blame creeps in first, because people unconsciously edit their own role.
Send the timeline out in advance. Nobody should be encountering the sequence of events for the first time in the room; that’s when defensiveness spikes.
During the Meeting
Open by naming the norm out loud: “We’re here to understand the system, not to evaluate anyone’s judgment.” It sounds unnecessary. It isn’t; restating it every time keeps it from decaying into a formality.
Walk the timeline chronologically. At each decision point, ask what information was available to the person at that moment, not what’s obvious in hindsight. This is the core discipline of blameless analysis: judging decisions by what was knowable at the time, not by the outcome.
Use “the system” and “the process” as the subject of sentences, not names. “The deploy pipeline allowed a change to skip staging” instead of “Priya skipped staging.” This isn’t euphemism; it’s accuracy, since the pipeline is what actually permitted it.
Capture contributing factors as a list, not a single root cause. Incidents are almost always the result of several small gaps lining up, so a stricter definition of “root cause” tends to stop the analysis one layer too early.
After the Meeting
Write the postmortem document in plain, specific language, and make it as widely readable as your access controls allow. The value of a postmortem compounds when other teams can learn from an incident they weren’t part of.
Turn contributing factors into tracked action items with owners and dates, not vague intentions. “Improve monitoring” isn’t an action item. “Add a staging-check gate to the deploy pipeline by [date]” is.
Follow up on those action items in a later review. This is where most postmortem processes quietly fail: the meeting happens, the document gets written, and the fixes never ship because nothing forces the follow-through.
Where This Fits Into a Broader SRE Practice
Blameless postmortems work best as part of a wider reliability discipline, not as an isolated ritual bolted onto incident response. Teams that treat postmortems seriously tend to also invest in the on-call structure, error budgets, and escalation paths that make the next incident easier to review honestly, because there’s less pressure to protect anyone.
If your team is running postmortems but still seeing the same categories of incidents recur, that’s often a signal the reliability practice around them needs support, not that the postmortem template needs another section. CDOps.tech’s Air Cover service embeds fractional SRE and interim DevOps expertise directly into teams that need this kind of structural backup without a full-time hire.
You can see how this plays out in practice in our case studies, or book a discovery call to talk through where your incident process is breaking down.
Frequently Asked Questions
How long should a blameless postmortem take? For most incidents, 45 to 60 minutes is enough once the timeline is prepared in advance. Complex, multi-team incidents may need longer, but the prep work, not the meeting length, is usually what determines quality.
Who should attend? Everyone directly involved in detecting, diagnosing, or resolving the incident, plus the facilitator. Keep it to people who add information; large audiences make people more guarded, not less.
What if leadership wants to know who’s responsible? Redirect that instinct toward the system-level fix, not a name. If leadership needs a person accountable for follow-through, that’s the action item owner: someone responsible for fixing the gap, not for having been in it.
Does every incident need a full postmortem? No. Set a threshold (customer impact, duration, severity) and use a lighter-weight writeup for smaller incidents. What matters is that the habit exists at some scale, not that every ticket gets the full process.
How do you know if your postmortems are actually blameless? Watch whether the same category of incident keeps recurring. If it does, the reviews are probably identifying symptoms, not systemic causes, often a sign that blame, even subtle, is still shaping what people are willing to say.
The Bottom Line
A good postmortem process can’t fix a reliability practice that isn’t there yet. Air Cover puts fractional SRE and interim DevOps expertise inside your team, no full-time hire required.
Case studies show the results. Book a discovery call to talk through your incident process.
Run postmortems that actually change something
Still seeing the same incidents resurface? CDOps Tech embeds fractional SRE and interim DevOps expertise into your team to close the reliability gaps your postmortems keep surfacing.

